
#What this article is about
I took one competitive programming problem and decided to look at which key ideas GPT-4 arrives at when solving it, which hints can steer it toward the correct solution, and which techniques (few-shot learning, for example) help it reach the correct solution of this problem. Based on all that, I analyze GPT-4's intelligence and how it could be improved. Then I propose a system for solving competitive programming problems based on a specially trained LLM. I give ideas on how the huge set of problems on CodeForces and similar sites could be used to collect high-quality training data and to improve this system iteratively and automatically.
Keep in mind that this article is no more than an idea with a bit of analysis, so it won't give you anything that works out of the box, but it will give you an interesting direction of thought. Please read it in exactly that light.
#Introduction
You've all seen those wonderful examples where ChatGPT is given a Leetcode problem and immediately writes a solution that works. It can even solve some medium or hard problems from after 2021, which couldn't have been in its training set. That's impressive, but I want to show that such systems have much more potential than just the "write code that solves this problem" pattern.
#The problem
I took the following problem: ITMO Academy: pilot course » Z-function » Step 4 » Practice » H. Sum of lengths of distinct substrings
Solve this problem using the z-function of a string. There are many ways to solve it, but as an exercise in using the z-function, try to come up with and implement exactly this kind of solution.
You are given a string s. Print the total length of all possible distinct substrings of this string.
Input: the only line of input contains s — a sequence of uppercase and lowercase Latin letters. The length of s does not exceed 8000 characters.
Output: print a single integer — the total length of all distinct substrings.
Examples: "BOBR" - 19, "ABACABA" - 73.
What the Z-function is
It's a function that takes a string and returns an array of numbers of the same length as the string. This array describes how many characters of the current suffix match the beginning of the string. This array can be computed in O(n) with a clever trick. The Z-function can be used to find a substring in a string in O(n), and in lots of other string problems.
Example: for the string ABACABA the Z-function is [0, 0, 1, 0, 3, 0, 1], because:
* 0 - the first element is always equal to       0 by definition
* 0 - string BACABA matches ABACABA in the first 0 characters
* 1 - string  ACABA matches ABACABA in the first 1 characters
* 0 - string   CABA matches ABACABA in the first 0 characters
* 3 - string    ABA matches ABACABA in the first 3 characters
* 0 - string     BA matches ABACABA in the first 0 characters
* 1 - string      A matches ABACABA in the first 1 characters
Suppose we want to find the string ab in the string abacaba. Then we can concatenate them with a unique character in between: ab$abacaba, and compute the z-function:
a b $ a b a c a b a
0 0 0 2 0 1 0 2 0 1
The places where 2 (the length of the string we're looking for) occurs are exactly the places where ab is a substring of abacaba.
I chose this problem because:
- Most likely neither it nor anything similar is in the training set, because it's hidden behind a registration wall.
- There's little information about the Z-function on the internet, so we can test not the memorized thinking patterns of people from the internet, but the neural network's own thinking abilities.
- It's relatively simple and relatively hard at the same time, ideal for testing machine intelligence.
- I solved it once (not with the most optimal method, by the way).
The gist of the solution
Every substring of the string starts at some position; let's look at one such position:
abacababa
    a
    ab
    aba
    abab
    ababa
Let's compute the Z-function of the suffix where all these strings start:
a b a b a
0 0 3 0 1
Here 3 means that the string aba matches the beginning of this string, and so do all its prefixes: a, ab, aba.
So if we're looking for unique strings, we can use the value of the Z-function to cross out the ones that will come up later:
abacababa
    a - - (counted twice)
    ab -
    aba -
    abab
    ababa
Then this suffix has only 2 unique strings: abab and ababa, and we can add up their lengths. The strings a, ab, aba will be counted when we look at the following suffixes.
Notice that we only need the maximum of the Z-function, and the sum of lengths can be computed with the arithmetic progression formula: take the sum of lengths of all prefixes of the suffix and subtract the sum of lengths of the repeated strings at its beginning.
Key points:
- Iterate over every suffix and compute its Z-function.
- Find the maximum value of the Z-function (excluding the zeroth element).
- If M is the length of the current suffix, add
M(M+1)/2 - Z_max*(Z_max+1)/2to the answer (I'll call this "the formula" for short).
These are the three key points you have to figure out to solve the problem correctly. In my analysis the neural network stumbled on every one of them, and I had to bend over backwards to make it use each next element in its solution.
This solution takes O(n^2) time and O(n) memory.
#Solving the problem
In the dialogues with the neural network it's worth reading my prompts, while ChatGPT's answers can be skimmed; I've highlighted in red the most important parts.
#2ChatGPT, solving it straight away
Let's just go ahead and ask ChatGPT straight away how to solve this problem, without the Z-function restriction:
Dialogue
You have this competitive programming task:
Given string S, calculate sum of lengths of unique substrings of that string.
How it can be solved in most efficient way? Write solution in C++.
One efficient solution to this problem is to use a data structure called a trie. A trie is a tree-like data structure that is commonly used for efficiently storing and searching for strings. We can construct a trie for the given string S, and then traverse the trie to count the total length of all unique substrings.
Here is the C++ code to solve this problem using a trie:
#include <bits/stdc++.h>
using namespace std;

const int MAXN = 1e6 + 5;

struct TrieNode {
    int child[26];
    bool is_end;
    TrieNode() {
        memset(child, -1, sizeof(child));
        is_end = false;
    }
};

TrieNode trie[MAXN];
int node_cnt = 1;

void insert(string& s) {
    int node = 0;
    for (char c : s) {
        int ch = c - 'a';
        if (trie[node].child[ch] == -1) {
            trie[node].child[ch] = node_cnt++;
        }
        node = trie[node].child[ch];
    }
    trie[node].is_end = true;
}

int dfs(int node, int depth) {
    int len = 0;
    for (int i = 0; i < 26; i++) {
        int child = trie[node].child[i];
        if (child != -1) {
            len += dfs(child, depth + 1);
        }
    }
    if (trie[node].is_end) {
        len += depth;
    }
    return len;
}

int main() {
    string s;
    cin >> s;
    int n = s.size();
    for (int i = 0; i < n; i++) {
        string sub = "";
        for (int j = i; j < n; j++) {
            sub += s[j];
            insert(sub);
        }
    }
    int ans = dfs(0, 0);
    cout << ans << endl;
    return 0;
}
In this solution, we first define a struct TrieNode to represent the nodes in the trie. Each node has an array child of size 26 (one for each possible lowercase letter) to store its children, and a boolean is_end to indicate whether the node represents the end of a word.
We then define a function insert to insert a string into the trie. Starting from the root node (which has index 0), we traverse the trie by following the appropriate child for each character in the string. If a child node does not exist for a particular character, we create a new node and assign it a new index node_cnt++. Finally, we set the is_end flag of the last node in the string to true.
After constructing the trie, we define a function dfs to recursively traverse the trie and count the total length of all unique substrings. We start from the root node and iterate over all its children. For each child node, we recursively call dfs with a depth incremented by 1, and add the returned value to len. If the current node represents the end of a word (i.e., is_end is true), we also add the current depth to len. Finally, we return len.
In the main function, we read in the input string s, and for each possible substring of s, we call the insert function to insert it into the trie. We then call dfs with the root node and depth 0, and output the returned value as the answer.
This solution has a time complexity of O(n^2), where n is the length of[MAX TOKENS REACHED]
Can you please using dynamic allocation to create a trie, and allow every possible char symbol instead of 26 small latin letters, and use long long to store result instead of int.
Sure! Here's the modified code that uses dynamic allocation to create the trie, supports all possible characters, and uses a long long to store the result:
#include <bits/stdc++.h>
using namespace std;

const int MAXN = 1e6 + 5;
const int MAXCHAR = 256;

struct TrieNode {
    int* child;
    bool is_end;
    TrieNode() {
        child = new int[MAXCHAR];
        memset(child, -1, sizeof(int) * MAXCHAR);
        is_end = false;
    }
    ~TrieNode() {
        delete[] child;
    }
};

TrieNode* trie[MAXN];
int node_cnt = 1;

void insert(string& s) {
    int node = 0;
    for (char c : s) {
        int ch = (int)c;
        if (trie[node]->child[ch] == -1) {
            trie[node]->child[ch] = node_cnt++;
            trie[node_cnt - 1] = new TrieNode();
        }
        node = trie[node]->child[ch];
    }
    trie[node]->is_end = true;
}

long long dfs(int node, int depth) {
    long long len = 0;
    for (int i = 0; i < MAXCHAR; i++) {
        int child = trie[node]->child[i];
        if (child != -1) {
            len += dfs(child, depth + 1);
        }
    }
    if (trie[node]->is_end) {
        len += (long long)depth;
    }
    return len;
}

int main() {
    string s;
    cin >> s;
    int n = s.size();
    trie[0] = new TrieNode();
    for (int i = 0; i < n; i++) {
        string sub = "";
        for (int j = i; j < n; j++) {
            sub += s[j];
            insert(sub);
        }
    }
    long long ans = dfs(0, 0);
    cout << ans << endl;
    for (int i = 0; i < node_cnt; i++) {
        delete trie[i];
    }
    return 0;
}
In this modified solution, we define a struct TrieNode as before, but now the child array is dynamically allocated using the new operator, and its size is set to MAXCHAR. We also add a destructor to the TrieNode class to properly deallocate the child array using the delete[] operator.
In the insert function, we use (int)c to convert the character c to an integer before indexing into the child array, since we now support all possible characters.
In the dfs function, we use a long long variable to store the total length of all unique substrings, since the sum can potentially exceed the range of an int. We also cast the depth variable to a long long when adding it to len, to avoid integer overflow.
In the main function, we initialize the root node of the trie using the new operator, and set its index to 0. After constructing the trie, we call the dfs function with the root node and depth 0, and output the returned value as the answer. Finally, we properly deallocate all dynamically allocated memory using the delete operator.
This solution has a time complexity of O(n^2), where n is the length of the input string s. The space complexity is also O(n^2), since there can be up to n^2 nodes in the trie[MAX TOKENS REACHED]
(Well, it wasn't quite straight away: I had to regenerate the answer several times and change the prompt. But in fact the network gives this solution often: I kept seeing that it wants to use exactly this one, and it talks about it from different angles.)
ChatGPT immediately writes a solution based on a suffix tree (a trie), and by the way it works correctly, but it needs a few tweaks, which I ask for in the next prompt. The trouble with this solution, though, is that it doesn't fit into the memory limit, because it needs O(n^2) memory. Even if you go to great lengths, 8000 characters squared still won't fit into 512 MB.
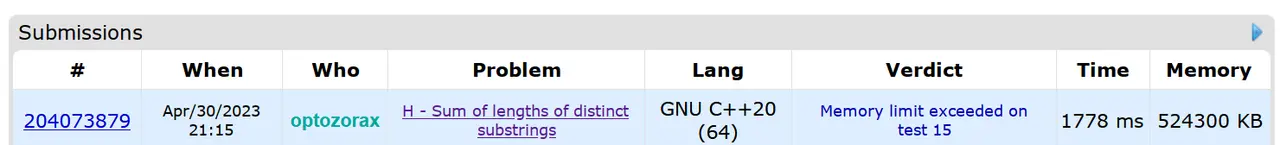

png
This solution was probably in the training set; it produced it way too easily.
Right here we can see the typical pattern of how LLMs solve programming problems: they write code straight away, with no reasoning and no analysis. How could this solution have been born inside matrix multiplications? I have no idea, and I don't believe such a function can be found and approximated well enough. I think this is the wrong way to do it: solving a problem should start with reasoning in the form of text, and only after the reasoning should the code be written. That way you'd get many more good solutions.
By the way, the magic prompt "think step by step" doesn't help much either.
#2ChatGPT, using the Z-function
Now let's ask it to solve this problem using the Z-function:
Dialogue
You have that competitive programming task:
Given string S, calculate sum of lengths of unique substrings of that string.
How would you solve it using Z-function in most efficient way? Think step-by-step.
To solve this problem efficiently using the Z-function, we can follow the steps given below:
-
First, we create an array
zof the same length as the input stringS. Thezarray will hold the Z-values for each position in the string. -
For each position
iin the input stringS, we compute the Z-value for the substring starting at that position. To do this, we compare the prefix ofSstarting at positioniwith the entire stringSand count the number of characters that match. We stop when we encounter a non-matching character or reach the end of the string. -
We sum up the Z-values for all positions in the
zarray, except for the first position, which corresponds to the entire input stringS. -
The sum obtained in the previous step is the desired result.
Here's the Python code to implement this approach:
def z_function(s):
    n = len(s)
    z = [0] * n
    l, r = 0, 0
    for i in range(1, n):
        if i <= r:
            z[i] = min(r - i + 1, z[i - l])
        while i + z[i] < n and s[z[i]] == s[i + z[i]]:
            z[i] += 1
        if i + z[i] - 1 > r:
            l, r = i, i + z[i] - 1
    return z

def unique_substring_lengths(s):
    z = z_function(s)
    return sum(z[1:]) + len(s)
In this implementation, the z_function function computes the Z-values for the input string s, and the unique_substring_lengths function computes the sum of lengths of unique substrings of s. The z array is used to keep track of the Z-values for each position in s. The sum of the Z-values for all positions in z, except for the first position, is the sum of lengths of all unique substrings of s. Adding the length of s itself gives us the total sum of lengths of all substrings of s.
It gives a solution that:
- Doesn't iterate over every suffix.
- Computes a sum and doesn't think about the maximum at all.
- And of course, there's no "formula" whatsoever.
The problem is that the network can't say "I don't know". I can't even imagine how, technically, it could ever tell what it knows and what it doesn't. It's not even a matter of training. Ideally, it should always say that it doesn't know exactly how to solve the problem with a given approach, and analyze every problem from scratch, instead of spitting out a solution straight away like this.
#2GPT-4, using the Z-function
Now let's try the more advanced GPT-4:
Dialogue
You have that competitive programming task:
Given string S, calculate sum of lengths of unique substrings of that string.
How would you solve it using Z-function in most efficient way? Think step-by-step.
Using the Z-function is a great choice for this problem. Here's a step-by-step guide on how to solve this competitive programming task most efficiently with the Z-function:
-
Understand the problem: Given a string S, we need to calculate the sum of lengths of unique substrings of that string.
-
Prepare the Z-function: The Z-function for a string S is an array of length n, where Z[i] is the length of the longest common prefix between S and the suffix of S starting at position i. The Z-function can be calculated in O(n) time complexity using Z-algorithm.
-
Initialize variables: Create a variable to store the sum of lengths of unique substrings, let's call it
sum_lengths. -
Iterate through the string S: For each index i (0 <= i < n), where n is the length of the string S, do the following:
a. Calculate the Z-array for the suffix starting at position i by using the Z-algorithm. This can be done by calling a helper function, e.g.,
z_array = calculate_z_array(S[i:]).b. For each element in the calculated Z-array, add the value to the
sum_lengthsvariable. Since the Z-array represents the longest common prefix between the original string and the suffixes, adding those values would result in the sum of lengths of unique substrings. Be careful not to count the Z[0] value, as it represents the entire suffix. -
Return the result: Return the
sum_lengthsvariable, which contains the sum of lengths of unique substrings of the given string S.
Here's a Python implementation of the approach described above:
def calculate_z_array(s):
    n = len(s)
    z = [0] * n
    l, r = 0, 0

    for i in range(1, n):
        if i > r:
            l, r = i, i
            while r < n and s[r - l] == s[r]:
                r += 1
            z[i] = r - l
            r -= 1
        else:
            k = i - l
            if z[k] < r - i + 1:
                z[i] = z[k]
            else:
                l = i
                while r < n and s[r - l] == s[r]:
                    r += 1
                z[i] = r - l
                r -= 1

    return z

def sum_unique_substrings_lengths(s):
    sum_lengths = 0
    n = len(s)

    for i in range(n):
        z_array = calculate_z_array(s[i:])
        sum_lengths += sum(z_array[1:])

    return sum_lengths

# Example usage
S = "ababa"
print(sum_unique_substrings_lengths(S))  # Output: 14
This implementation has a time complexity of O(n^2), as we calculate the Z-array for each suffix of the string.
Interestingly, GPT-4 somehow figures out that this problem can't be solved in O(n) with a single Z-function computation, and starts iterating over all possible suffixes! At that moment I thought I was wasting my time on nonsense, and that maybe the answer to every question really is to stack more layers and feed in more input data?
Possible reasons
After writing this article I googled it and found that there are lots of articles on the internet about how to find the number of unique substrings using the Z-function, for example:
It's also obvious where the network got the trie solutions from:
And I haven't even looked at the Leetcode discussions, which hold a million different variations of solutions to the same problem; this locked problem surely has something about the Z-function too: leetcode.
Perhaps, thanks to the larger number of parameters, the network finally memorized one of the solutions described somewhere here, along with solutions to other similar problems.
But then it goes back to summing the values of the Z-function, so the robot uprising is postponed.
And by the way, the solution looks like valid reasoning, but in fact it's just a nicely formatted output of a "ready-made" answer. No "think step by step" at all.
The solution was stated here:
b. For each element in the calculated Z-array, add the value to the
sum_lengthsvariable.
And everything after that is just a justification of this solution; luckily, the network is good at inventing plausible justifications for anything:
Since the Z-array represents the longest common prefix between the original string and the suffixes, adding those values would result in the sum of lengths of unique substrings.
After that I kept talking to the network, running its solution and sometimes giving hints:
Dialogue
For string "BOBR" it should output 19, but this program outputs 1. Where is the mistake?
Apologies for the confusion. I made an error in my previous response. You're correct that the output should be 19 for the string "BOBR". Here's the corrected solution using the Z-function:
-
Initialize the variable
sum_lengthsto store the sum of lengths of unique substrings. -
Iterate through the string S: For each index i (0 <= i < n), where n is the length of the string S, do the following:
a. Calculate the Z-array for the suffix starting at position i by using the Z-algorithm. This can be done by calling a helper function, e.g.,
z_array = calculate_z_array(S[i:]).b. Instead of summing up the Z-array values, we need to find the count of unique lengths in the Z-array. This can be achieved by creating a set and adding all Z-array values to it except the first value (Z[0]).
-
Return the result: Return the sum of all elements in the set, which contains the unique lengths of common prefixes.
Here's the corrected Python implementation of the approach:
def calculate_z_array(s):
    n = len(s)
    z = [0] * n
    l, r = 0, 0

    for i in range(1, n):
        if i > r:
            l, r = i, i
            while r < n and s[r - l] == s[r]:
                r += 1
            z[i] = r - l
            r -= 1
        else:
            k = i - l
            if z[k] < r - i + 1:
                z[i] = z[k]
            else:
                l = i
                while r < n and s[r - l] == s[r]:
                    r += 1
                z[i] = r - l
                r -= 1

    return z

def sum_unique_substrings_lengths(s):
    sum_lengths = 0
    n = len(s)

    for i in range(n):
        z_array = calculate_z_array(s[i:])
        unique_lengths = set(z_array[1:])
        sum_lengths += sum(unique_lengths)

    return sum_lengths

# Example usage
S = "BOBR"
print(sum_unique_substrings_lengths(S))  # Output: 19
This implementation still has a time complexity of O(n^2), but now it should provide the correct output for the given input strings.
It still outputs 1. Note, that Z-function for "BOBR" is [0, 0, 1, 0], so you can't use sum of values of Z-function. You should use another approach.
You are correct. I apologize for my misunderstanding. I appreciate your patience. Let's try a different approach using the Z-function, which allows us to calculate the number of unique substrings in a more efficient manner.
-
Initialize a variable
sum_lengthsto store the sum of lengths of unique substrings. -
Iterate through the string S:
For each index i (0 <= i < n), where n is the length of the string S, do the following:
a. Create a new string
tempby concatenating the original string S with a unique delimiter and the substring S[i:]. For example, if S = "BOBR" and i = 1, then temp = "BOBR$OBR".b. Calculate the Z-array for the new string
tempusing the Z-algorithm.c. Iterate through the Z-array and for each Z[i] value, check if Z[i] + i <= n, where n is the length of the original string S. If this condition is satisfied, it means that the common prefix is a unique substring. Add the length of this common prefix (Z[i]) to
sum_lengths. -
Return the result: Return the
sum_lengthsvariable, which contains the sum of lengths of unique substrings of the given string S.
Here's the Python implementation for this approach:
def calculate_z_array(s):
    n = len(s)
    z = [0] * n
    l, r = 0, 0

    for i in range(1, n):
        if i > r:
            l, r = i, i
            while r < n and s[r - l] == s[r]:
                r += 1
            z[i] = r - l
            r -= 1
        else:
            k = i - l
            if z[k] < r - i + 1:
                z[i] = z[k]
            else:
                l = i
                while r < n and s[r - l] == s[r]:
                    r += 1
                z[i] = r - l
                r -= 1

    return z

def sum_unique_substrings_lengths(s):
    sum_lengths = 0
    n = len(s)

    for i in range(n):
        temp = s + '$' + s[i:]
        z_array = calculate_z_array(temp)

        for j in range(len(z_array)):
            if z_array[j] + j <= n:
                sum_lengths += z_array[j]

    return sum_lengths

# Example usage
S = "BOBR"
print(sum_unique_substrings_lengths(S))  # Output: 19
This implementation has a time complexity of O(n^2) and should provide the correct output for the given input strings.
This now outputs 4, which is better, but still wrong. Can you think which information Z-function tells us? Maybe we should not add Z-function, but substract? How many there are substrings of a string with length N? Can you use that information?
I apologize for the confusion in my previous responses. Let's approach the problem with a better understanding of the Z-function and the task at hand.
For a string of length N, there are (N * (N + 1)) / 2 total substrings. This includes both unique and non-unique substrings. To find the sum of lengths of unique substrings, we can calculate the total number of substrings and subtract the number of repeated substrings. The Z-function helps us identify these repeated substrings.
Here's the step-by-step approach:
-
Initialize a variable
sum_lengthsto store the sum of lengths of unique substrings. Set its initial value to (N * (N + 1)) / 2, where N is the length of the string S. -
Iterate through the string S:
For each index i (0 <= i < n), where n is the length of the string S, do the following:
a. Create a new string
tempby concatenating the original string S with a unique delimiter and the substring S[i:]. For example, if S = "BOBR" and i = 1, then temp = "BOBR$OBR".b. Calculate the Z-array for the new string
tempusing the Z-algorithm.c. Iterate through the Z-array and for each Z[i] value, check if Z[i] + i <= n, where n is the length of the original string S. If this condition is satisfied, it means that the common prefix is a repeated substring. Subtract the length of this common prefix (Z[i]) from
sum_lengths. -
Return the result: Return the
sum_lengthsvariable, which contains the sum of lengths of unique substrings of the given string S.
Here's the Python implementation for this approach:
def calculate_z_array(s):
    n = len(s)
    z = [0] * n
    l, r = 0, 0

    for i in range(1, n):
        if i > r:
            l, r = i, i
            while r < n and s[r - l] == s[r]:
                r += 1
            z[i] = r - l
            r -= 1
        else:
            k = i - l
            if z[k] < r - i + 1:
                z[i] = z[k]
            else:
                l = i
                while r < n and s[r - l] == s[r]:
                    r += 1
                z[i] = r - l
                r -= 1

    return z

def sum_unique_substrings_lengths(s):
    n = len(s)
    sum_lengths = (n * (n + 1)) // 2

    for i in range(n):
        temp = s + '$' + s[i:]
        z_array = calculate_z_array(temp)

        for j in range(len(z_array)):
            if z_array[j] + j <= n:
                sum_lengths -= z_array[j]

    return sum_lengths

# Example usage
S = "BOBR"
print(sum_unique_substrings_lengths(S))  # Output: 19
This implementation has a time complexity of O(n^2) and should now provide the correct output for the given input strings.
It started producing some nonsense about a set of Z-function values, then some strange concatenation. After that it came up with a piece of the formula (with my hint), but applied it completely wrong.
I continue the conversation:
Dialogue
This now outputs 6. Still not correct answer. Can you please explain how exactly does Z-function helps us identify repeated strings, based on a definition of the Z-function? Maybe it's maximum, or minimum can help us?
I apologize for the previous mistakes. Upon further analysis, I realize that using the Z-function in this context is not the most efficient way to solve the problem. Let's switch to another approach that works more efficiently: the Trie data structure.
A Trie is a tree-like data structure that is used to store a dynamic set of strings. The key benefit of using a Trie is that it allows for efficient searching and insertion of strings.
Here's the step-by-step approach:
- Implement a Trie data structure: [INTERRUPTED]
Z-function is most efficient, it takes O(n^2) time, but O(n) memory, when Trie uses same O(n^2) time, but O(n^2) memory, my programming competition don't allowed that much memory.
You're correct that the Z-function has better memory complexity than a Trie. I apologize for the confusion earlier. Let's return to the Z-function approach and refine it.
To calculate the sum of lengths of unique substrings using the Z-function, we can calculate the number of repeated substrings for each index and subtract that count from the total substrings. We can utilize the maximum value of the Z-array to calculate the number of repeated substrings.
Here's the step-by-step approach:
-
Initialize a variable
sum_lengthsto store the sum of lengths of unique substrings. Set its initial value to (N * (N + 1)) / 2, where N is the length of the string S. -
Iterate through the string S:
For each index i (0 <= i < n), where n is the length of the string S, do the following:
a. Calculate the Z-array for the suffix starting at position i by using the Z-algorithm.
b. Find the maximum value in the Z-array (ignoring the first element, Z[0]).
c. Subtract the maximum value from the total substrings for the current index (n - i), and add the result to
sum_lengths. -
Return the result: Return the
sum_lengthsvariable, which contains the sum of lengths of unique substrings of the given string S.
Here's the Python implementation for this approach:
def calculate_z_array(s):
    n = len(s)
    z = [0] * n
    l, r = 0, 0

    for i in range(1, n):
        if i > r:
            l, r = i, i
            while r < n and s[r - l] == s[r]:
                r += 1
            z[i] = r - l
            r -= 1
        else:
            k = i - l
            if z[k] < r - i + 1:
                z[i] = z[k]
            else:
                l = i
                while r < n and s[r - l] == s[r]:
                    r += 1
                z[i] = r - l
                r -= 1

    return z

def sum_unique_substrings_lengths(s):
    n = len(s)
    sum_lengths = 0

    for i in range(n):
        z_array = calculate_z_array(s[i:])
        max_z = max(z_array[1:])
        sum_lengths += (n - i) - max_z

    return sum_lengths

# Example usage
S = "BOBR"
print(sum_unique_substrings_lengths(S))  # Output: 19
This implementation has a time complexity of O(n^2) and memory complexity of O(n), which should be suitable for the given programming competition constraints.
It realized that life is futile and somehow started talking about the trie approach, for which it actually knows the solution. I stopped it and said that this approach needs O(n^2) memory, so it doesn't suit us.
And then, wow, it seems my words about the maximum gave it a bright idea. But the formula is still wrong, although conceptually it's very much on the right track!
sum_lengths += (n - i) - max_z
I figured I'd soon run out of the 8k-token context, so I decided to see what would happen if I gave it the correct formula without any explanation:
Dialogue
This prints 8, which is not correct. The correct formula is sum_lengths += (n-i)*(n-i+1)/2 - max_z*(max_z+1)/2.
I apologize for the confusion earlier. You are correct, the formula you provided accounts for the lengths of unique substrings more accurately. Here's the corrected implementation using the Z-function and the formula you provided:
def calculate_z_array(s):
    n = len(s)
    z = [0] * n
    l, r = 0, 0

    for i in range(1, n):
        if i > r:
            l, r = i, i
            while r < n and s[r - l] == s[r]:
                r += 1
            z[i] = r - l
            r -= 1
        else:
            k = i - l
            if z[k] < r - i + 1:
                z[i] = z[k]
            else:
                l = i
                while r < n and s[r - l] == s[r]:
                    r += 1
                z[i] = r - l
                r -= 1

    return z

def sum_unique_substrings_lengths(s):
    n = len(s)
    sum_lengths = 0

    for i in range(n):
        z_array = calculate_z_array(s[i:])
        max_z = max(z_array[1:])
        sum_lengths += (n - i) * (n - i + 1) // 2 - max_z * (max_z + 1) // 2

    return sum_lengths

# Example usage
S = "BOBR"
print(sum_unique_substrings_lengths(S))  # Output: 19
This implementation has a time complexity of O(n^2) and memory complexity of O(n), which should be suitable for the given programming competition constraints. The output for the input string "BOBR" is now correct.
It fails:
    max_z = max(z_array[1:])
ValueError: max() arg is an empty sequenceI apologize for the oversight. To handle the case where the z_array has only one element, we can add a conditional check to ensure it has more than one element before finding the max. Here's the updated implementation:
def calculate_z_array(s):
    n = len(s)
    z = [0] * n
    l, r = 0, 0

    for i in range(1, n):
        if i > r:
            l, r = i, i
            while r < n and s[r - l] == s[r]:
                r += 1
            z[i] = r - l
            r -= 1
        else:
            k = i - l
            if z[k] < r - i + 1:
                z[i] = z[k]
            else:
                l = i
                while r < n and s[r - l] == s[r]:
                    r += 1
                z[i] = r - l
                r -= 1

    return z

def sum_unique_substrings_lengths(s):
    n = len(s)
    sum_lengths = 0

    for i in range(n):
        z_array = calculate_z_array(s[i:])
        max_z = max(z_array[1:]) if len(z_array) > 1 else 0
        sum_lengths += (n - i) * (n - i + 1) // 2 - max_z * (max_z + 1) // 2

    return sum_lengths

# Example usage
S = "BOBR"
print(sum_unique_substrings_lengths(S))  # Output: 19
This implementation should now work correctly for all cases, including cases where the z_array has only one element. The time complexity remains O(n^2), and the memory complexity is O(n), which should be suitable for the programming competition constraints.
That code is correct. Can you explain formula, why exactly it uses max_z, what is that thing is squaring it, and why it sums something and substracts something? I can't understand what that has to do with sum of lengths of unique substrings.
Certainly! Let's break down the formula and explain its components:
sum_lengths += (n - i) * (n - i + 1) // 2 - max_z * (max_z + 1) // 2The formula calculates the sum of lengths of unique substrings for each suffix of the input string S. We iterate through the string, starting with the entire string as a suffix and moving towards shorter suffixes.
(n - i) * (n - i + 1) // 2: This part of the formula calculates the total number of substrings for the current suffix. We use the formula for the sum of the first n natural numbers (n * (n + 1) / 2) to calculate this. Here, n - i represents the length of the current suffix. For example, if the input string is "BOBR" and i = 1, we are considering the suffix "OBR", which has a length of 3. The total number of substrings for this suffix is 3 * (3 + 1) / 2 = 6.
max_z: This variable represents the length of the longest common prefix between the current suffix and any of its smaller substrings. By calculating the Z-array for the current suffix, we can find the maximum value (excluding Z[0]), which represents the longest repeated substring within the current suffix.
max_z * (max_z + 1) // 2: This part of the formula calculates the sum of lengths of the repeated substrings (non-unique substrings) for the current suffix. We multiply max_z by (max_z + 1) / 2, which is the sum of the first max_z natural numbers. This gives us the total length of the repeated substrings.
Finally, we subtract the sum of lengths of the repeated substrings from the total number of substrings for the current suffix to obtain the sum of lengths of unique substrings for that suffix:
sum_lengths += (n - i) * (n - i + 1) // 2 - max_z * (max_z + 1) // 2By iterating through the string and performing this calculation for each suffix, we can compute the sum of lengths of unique substrings for the entire input string S.
In the end it made a small runtime error, but managed to fix the code and give a fully working, correct and optimal solution. And then it also explained well why the formula is the way it is.
We can see that the network can't think: it gives an answer straight away, but it's still very smart! It can find the solution if you give it the right hints, and it can fix code based on an error message. It's an incredible foundation, and it seems that only a little effort in the right direction is needed to make it even smarter.
From here on in the analysis I'll only talk to GPT-4.
#2Summarizing the solution
Next I thought the network would be able to summarize the whole solution well in one sentence, so that I could give it this sentence as input and it would produce the solution in another dialogue. This is about my attempts to generate training data, which I'll describe in more detail later.
In the end I couldn't make it give the solution in one sentence, even after very many attempts. Even when I wrote such a sentence by hand myself, it didn't work.
One of the examples:
Dialogue
Can you please summarize full idea to solve that task in one sentence?
#2Few-shot learning
I saw this technique somewhere: first you give a good solution to a similar problem, then your problem, and the network performs much better by working by analogy.
I decided to try the same. I found a similar problem about palindromes and the Z-function, and then took the hard road: first I wrote a solution to the current problem and asked it to solve the palindrome problem, and then I gave the network the palindrome solution, written in the right style, to solve the sum problem. Not quite the right way to do it, but it is what it is.
Dialogue
Teacher: You have that competitive programming task: "You given string S, find length of the longest its substing that is a palindrome.". How would you solve it using Z-function in most efficient way? Think step-by-step.
Gaalian: Let's consider different usages of Z-function in this task:
- Z-function of just the string.
- Z-function of all suffixes of the string.
- Z-function of the reversed string concatenated to the original string with a special character in between.
- Z-function of each prefix and its reversed version concatenated.
Let's analyze them:
- This is not useful since Z-function is related to the longest common prefix and has nothing to do with palindromes.
- Similar to option 1, this also doesn't provide any useful information about palindromes.
- This option seems interesting. Suppose the original string is S, and we create a new string R = S + '$' + S[::-1]. Let's consider some examples:
- S = "abba", R = "abba$abba". In this case, the Z-function can detect the whole palindrome, but it doesn't work for odd length palindromes.
- S = "aba", R = "aba$aba". The Z-function will not be able to detect the longest palindrome here. So, while this approach may work for even length palindromes, it doesn't work for odd length palindromes.
- This option allows us to find the longest palindrome for each prefix of the string. For each prefix, we can create a new string R = P + '$' + P[::-1], where P is the current prefix of S. Then, we calculate the Z-function for R. The longest palindrome can be found by calculating the longest common prefix between P and its reversed version. The only issue with this approach is that it has a time complexity of O(n^2), as we need to calculate the Z-function for each prefix.
Considering the options, the most efficient way possible using only Z-function seems to be option 4.
So, the complete solution using Z-function will look like this:
- Initialize a variable max_palindrome_length to store the longest palindrome length
- Iterate through each prefix of the string S
- Create a new string R by concatenating the current prefix, a special character, and the reversed prefix
- Calculate the Z-function for R
- Find the maximum value in the Z-function array (ignoring the first element)
- Update max_palindrome_length with the maximum of the current maximum value and the previously stored max_palindrome_length
- The max_palindrome_length variable now stores the length of the longest palindrome substring in S
Teacher: Good. Now solve another competitive programming task: "Given string S, calculate sum of lengths of unique substrings of that string.". Solve it in the most efficient way possible using only Z-function.
---
Can you answer as the Gaalian with the same style of thinking?
Gaalian: Let's consider different usages of Z-function in this task:
- Z-function of just the string.
- Z-function of all suffixes of the string.
- Z-function of each prefix and its reversed version concatenated.
- Z-function of the reversed string concatenated to the original string with a special character in between.
Let's analyze them:
- This is not useful since Z-function is related to the longest common prefix and has nothing to do with unique substrings directly.
- This option allows us to find the longest common prefix for each suffix of the string. By calculating the Z-function for each suffix of S, we can determine the number of unique substrings for each suffix. This method can help us to calculate the sum of lengths of unique substrings efficiently.
- This option, similar to option 1, doesn't provide any useful information about unique substrings.
- This option is also not helpful in calculating the sum of lengths of unique substrings.
Considering the options, the most efficient way possible using only Z-function seems to be option 2.
So, the complete solution using Z-function will look like this:
- Initialize a variable sum_of_unique_substrings_length to store the sum of lengths of unique substrings
- Iterate through each suffix of the string S
- Calculate the Z-function for the current suffix
- The number of unique substrings for the current suffix is equal to the length of the suffix minus the maximum value in the Z-function array (ignoring the first element)
- Update sum_of_unique_substrings_length by adding the number of unique substrings for the current suffix
- The sum_of_unique_substrings_length variable now stores the sum of lengths of unique substrings in S
In the end it arrived at the maximum, but not at the "formula", and it didn't even consider examples the way it was done in the original prompt. Although even in the original prompt GPT-4 wrote the examples just for show, in mine they were at least somehow used inside the reasoning.
Then I asked it to analyze this solution and compare it with the naive one on the string "BOBR", and it produced the following masterpiece:
Dialogue
Can you find sum of lengths of unique substrings of string "BOBR" using that algorithm, and then check if you right using naive approach, and then correct yourself if you are not right.
Let's first use the Z-function-based algorithm to find the sum of lengths of unique substrings for the string "BOBR":
-
For suffix "BOBR" (z = [0, 0, 1, 0]): Unique substrings: "B", "O", "R", "BO", "OB", "BR", "BOB", "OBR", "BOBR" (9 substrings) Number of unique substrings = length of the suffix (4) - max value in the Z-function array (1) = 3
-
For suffix "OBR" (z = [0, 0, 0]): Unique substrings: "O", "B", "R", "OB", "BR", "OBR" (6 substrings) Number of unique substrings = length of the suffix (3) - max value in the Z-function array (0) = 3
-
For suffix "BR" (z = [0, 0]): Unique substrings: "B", "R", "BR" (3 substrings) Number of unique substrings = length of the suffix (2) - max value in the Z-function array (0) = 2
-
For suffix "R" (z = [0]): Unique substrings: "R" (1 substring) Number of unique substrings = length of the suffix (1) - max value in the Z-function array (0) = 1
Sum of lengths of unique substrings = 3 + 3 + 2 + 1 = 9
Now, let's use the naive approach to confirm the result:
All possible substrings of "BOBR":
- "B"
- "O"
- "R"
- "BO"
- "OB"
- "BR"
- "BOB"
- "OBR"
- "BOBR"
All substrings are unique, so the sum of lengths of unique substrings is equal to the total length of all substrings = 1 + 1 + 1 + 2 + 2 + 2 + 3 + 3 + 4 = 9
Both the Z-function-based algorithm and the naive approach produce the same result, which is 9. The algorithm seems to work correctly for the given input.
This is just beautiful: 1 + 1 + 1 + 2 + 2 + 2 + 3 + 3 + 4 = 9. Apparently the training set had too many comparisons of two solutions where both always turned out to be correct, so the network fell for this terrible cognitive bias. And this result reproduced for me time after time: the network always said that both the naive and the proposed solutions were correct.
All in all, this didn't really work: the network did what I did, but just for show, not for reasoning. It didn't help it invent the formula, it only helped it arrive at the maximum (and even the maximum was already in the previous problem), which it had arrived at before anyway.
#2Continuing a pre-written solution
I decided to take one last path: I'd write by hand all the reasoning that leads to the correct solution, and then gradually remove sentences from the end to see from which point the network is able to reach the correct solution. I recommend reading the prompt carefully.
Dialogue
Teacher: You have that competitive programming task: "Given string S, calculate sum of lengths of unique substrings of that string.". How would you solve it using Z-function in most efficient way? Think step-by-step.
Gaalian: We can consider different usages of Z-function in that task:
- Z-function of just the string.
- Z-function of all suffixes of the string.
Let's analyze them:
- That can be used only on definition, and definition of Z-function has nothing about unique substrings or sum of their lengths, so it wouldn't give us much.
- That can tell us how many strings match with currenct suffix, and that's interesting. For suffix "ababa" we will get Z-function [0, 0, 2, 0, 1]. If we consider all prefixes of that suffix, then we will get "a", "ab", "aba", "abab", "ababa". And we know that "a" and "ab" is repeated in the other suffixes. We can sum lengths of current prefix and substract lengths of strings that repeated in the current suffix. We have only two useful numbers in Z-function: 2 and 1, first number means strings "ab" and "a", second number means "a". Each number, that is smaller than the maximum will not be useful, because it's already considered in the maximum number. So we will need to use only maximum number of the suffix Z-function. So, we need to calc sum of lengths of current prefixes minus sum of lengths of repeated strings. Will be "ab" and "a" considered as unique strings later? Yes, when they will be current suffix to analyze.
So, the complete solution will look like this:
- Iterate through each suffix, length of current suffix is M.
- For each suffix calculate Z-function. ...
---
Can you please continue Gaalian solution?
Certainly! Continuing with Gaalian's solution:
-
For each suffix, calculate the Z-function.
-
Find the maximum value in the Z-function array, excluding the first element (which is always the length of the string itself). Let this value be
max_z. -
Calculate the sum of lengths of all unique substrings for the current suffix. This can be done as the sum of all integers from 1 to M (the length of the current suffix), then subtract the sum of all integers from 1 to
max_z. The formula for the sum of first N integers isN * (N + 1) / 2. -
Add the result to the total sum of unique substrings.
-
Repeat the process for all suffixes of the string.
-
Return the total sum of unique substrings.
Here's a Python implementation of the above solution:
def z_function(s):
    n = len(s)
    z = [0] * n
    l, r = 0, 0
    for i in range(1, n):
        if i > r:
            l, r = i, i
            while r < n and s[r - l] == s[r]:
                r += 1
            z[i] = r - l
            r -= 1
        else:
            k = i - l
            if z[k] < r - i + 1:
                z[i] = z[k]
            else:
                l = i
                while r < n and s[r - l] == s[r]:
                    r += 1
                z[i] = r - l
                r -= 1
    return z

def unique_substrings(s):
    total_sum = 0
    for i in range(len(s)):
        suffix = s[i:]
        z_arr = z_function(suffix)
        max_z = max(z_arr[1:])
        M = len(suffix)
        total_sum += (M * (M + 1) // 2) - (max_z * (max_z + 1) // 2)
    return total_sum

S = "ababa"
print(unique_substrings(S))
This implementation calculates the sum of lengths of unique substrings for the given string S using the Z-function in an efficient way.
Legendary! It came up with the "formula" from a text description!!! Hooray, I managed to make it do this at least somehow. Now there's motivation to keep going.
Next I'll remove sentences little by little; the removed text will be struck through. This is to save your time and attention.
Dialogue
Teacher: You have that competitive programming task: "Given string S, calculate sum of lengths of unique substrings of that string.". How would you solve it using Z-function in most efficient way? Think step-by-step.
Gaalian: We can consider different usages of Z-function in that task:
- Z-function of just the string.
- Z-function of all suffixes of the string.
Let's analyze them:
- That can be used only on definition, and definition of Z-function has nothing about unique substrings or sum of their lengths, so it wouldn't give us much.
- That can tell us how many strings match with currenct suffix, and that's interesting. For suffix "ababa" we will get Z-function [0, 0, 2, 0, 1]. If we consider all prefixes of that suffix, then we will get "a", "ab", "aba", "abab", "ababa". And we know that "a" and "ab" is repeated in the other suffixes. We can sum lengths of current prefix and substract lengths of strings that repeated in the current suffix. We have only two useful numbers in Z-function: 2 and 1, first number means strings "ab" and "a", second number means "a". Each number, that is smaller than the maximum will not be useful, because it's already considered in the maximum number. So we will need to use only maximum number of the suffix Z-function. So, we need to calc sum of lengths of current prefixes minus sum of lengths of repeated strings. Will be "ab" and "a" considered as unique strings later? ...
Yes, when they will be current suffix to analyze.
So, the complete solution will look like this:
Iterate through each suffix, length of current suffix is M.For each suffix calculate Z-function.
---
Can you please continue Gaalian solution from "..."?
Yes, let's continue Gaalian's solution from "...":
So, to reiterate, we have determined that we should focus on the maximum value of the Z-function for each suffix. Now, let's proceed with the algorithm:
-
Initialize a variable
total_unique_substringsto store the sum of lengths of unique substrings. Set its initial value to 0. -
Iterate through the string
Sfrom the beginning to the end. For each character at positioni, consider the suffix of the string starting at positioni. Calculate the Z-function for that suffix. -
Find the maximum value of the Z-function for the current suffix, excluding the first element (which is always equal to the length of the string). Let's call this value
max_z. -
Calculate the sum of lengths of all possible substrings within the current suffix. This can be found using the formula
n * (n + 1) / 2, wherenis the length of the current suffix. -
Calculate the sum of lengths of the substrings repeated in the current suffix. This can be found using the formula
max_z * (max_z + 1) / 2. -
Subtract the sum of lengths of the repeated substrings (from step 5) from the sum of lengths of all possible substrings within the current suffix (from step 4). This will give you the sum of lengths of unique substrings for the current suffix.
-
Add the sum of lengths of unique substrings for the current suffix (from step 6) to the
total_unique_substrings. -
Repeat steps 2-7 for all characters in the string
S. -
After iterating through the entire string, the value of
total_unique_substringswill be the sum of lengths of unique substrings in the given stringS.
By following this algorithm, we efficiently calculate the sum of lengths of unique substrings using the Z-function.
It managed to continue to the correct solution. I'm removing more, but I had to add a little to make it work, because I saw that the network just wasn't getting going (oh, prompt engineering):
Dialogue
Teacher: You have that competitive programming task: "Given string S, calculate sum of lengths of unique substrings of that string.". How would you solve it using Z-function in most efficient way? Think step-by-step.
Gaalian: We can consider different usages of Z-function in that task:
- Z-function of just the string.
- Z-function of all suffixes of the string.
Let's analyze them:
- That can be used only on definition, and definition of Z-function has nothing about unique substrings or sum of their lengths, so it wouldn't give us much.
- That can tell us how many strings match with currenct suffix, and that's interesting. For suffix "ababa" we will get Z-function [0, 0, 2, 0, 1]. If we consider all prefixes of that suffix, then we will get "a", "ab", "aba", "abab", "ababa". And we know that "a" and "ab" is repeated in the other suffixes. We can sum lengths of current prefix and substract lengths of strings that repeated in the current suffix. We have only two useful numbers in Z-function: 2 and 1, first number means strings "ab" and "a", second number means "a". "a" is already considered in 2, so 1 ...
Each number, that is smaller than the maximum will not be useful, because it's already considered in the maximum number. So we will need to use only maximum number of the suffix Z-function. So, we need to calc sum of lengths of current prefixes minus sum of lengths of repeated strings. Will be "ab" and "a" considered as unique strings later? Yes, when they will be current suffix to analyze.
So, the complete solution will look like this:
Iterate through each suffix, length of current suffix is M.For each suffix calculate Z-function.
---
Can you please continue Gaalian solution from "..."?
Gaalian: Sure. So 1 doesn't give us any new information. Hence, we should only consider the maximum value from the Z-function of the current suffix. In this case, it's 2. Now let's calculate the sum of lengths of unique substrings for the current suffix "ababa":
Total lengths of all prefixes: 1 + 2 + 3 + 4 + 5 = 15 Lengths of repeated substrings: 1 + 2 = 3
Sum of lengths of unique substrings for "ababa": 15 - 3 = 12
We can apply this approach to all the suffixes of the string S.
Here's the step-by-step solution using Z-function:
- Initialize the total_sum variable to 0.
- Iterate through all suffixes of the given string S:
- a. For each suffix, calculate its Z-function.
- b. Find the maximum value in the Z-function of the current suffix.
- c. Calculate the sum of lengths of all prefixes of the current suffix.
- d. Subtract the sum of lengths of repeated substrings (based on the maximum value from the Z-function) from the sum of lengths of all prefixes.
- e. Add the result to the total_sum.
- Return the total_sum, which is the sum of lengths of unique substrings of the given string S.
By following this algorithm, we can efficiently calculate the sum of lengths of unique substrings using the Z-function.
Can you tell how exactly to do step 2 d?
Certainly! In step 2d, we need to subtract the sum of lengths of repeated substrings from the sum of lengths of all prefixes. Here's how to do it:
-
Calculate the sum of lengths of all prefixes of the current suffix. This can be done by simply using the formula: n * (n + 1) / 2, where n is the length of the current suffix.
-
Calculate the sum of lengths of repeated substrings based on the maximum value from the Z-function. Let's call the maximum value from the Z-function max_z. This max_z value represents the longest repeated substring present in the current suffix. The substrings that are repeated will have lengths from 1 to max_z. To calculate the sum of lengths of these repeated substrings, we can again use the formula: max_z * (max_z + 1) / 2.
-
Subtract the sum of lengths of repeated substrings from the sum of lengths of all prefixes. To do this, simply subtract the result from step 2 from the result of step 1.
Here's the updated step 2d:
2d. Subtract the sum of lengths of repeated substrings (based on the maximum value from the Z-function) from the sum of lengths of all prefixes:
- i. Calculate the sum of lengths of all prefixes using the formula: n * (n + 1) / 2, where n is the length of the current suffix.
- ii. Calculate the sum of lengths of repeated substrings using the formula: max_z * (max_z + 1) / 2, where max_z is the maximum value from the Z-function of the current suffix.
- iii. Subtract the result from step ii from the result of step i to get the sum of lengths of unique substrings for the current suffix.
Following these steps will help you perform step 2d correctly in the algorithm.
This is the limit beyond which it can still arrive at the maximum, but can't come up with the formula. I'm especially impressed by how exactly it guessed the maximum from such a hint.
And let me stress once again that GPT-4 is extremely smart! Being able to continue a correct solution from this kind of text reasoning is good work. All that's left is to teach it to think this way, and it will be able to solve problems.
Self-criticism
I realized all this only after writing this article. Redoing it is too expensive, and it seems you can always find nitpicks like these and never get an article like this done. But I can't leave out the self-criticism.
It was able to come up with the formula because I wrote We can sum lengths of current prefix and substract lengths of strings that repeated in the current suffix, and as I can see, I didn't derive this from my previous reasoning in any way. My reasoning is aimed only at arriving at taking the maximum. So it came up with the formula in a not entirely fair way. You could say I fell for a cognitive bias and kept searching until I saw what I wanted to see.
Also, my "reasoning" (post-factum reasoning, so to speak) about solving this problem isn't written in the best way; a much more elegant and correct iterative line of reasoning is given on e-maxx.ru (in Russian):
Given a string
sof lengthn. We need to count the number of its distinct substrings.We will solve this problem iteratively. Namely, we will learn how, knowing the current number of distinct substrings, to recompute this number when one character is appended to the end.
So, let
kbe the current number of distinct substrings of the strings, and we append the charactercto the end. Obviously, as a result some new substrings ending in this new characterccould have appeared (namely, all substrings ending in this character that haven't occurred before).Take the string
t=s+cand reverse it (write its characters in reverse order). Our task is to count how many prefixes of the string t do not occur anywhere else in it. But if we compute the Z-function for the stringtand find its maximum valuez_max, then, obviously, the prefix oftof lengthz_maxoccurs int(not at the beginning), but no longer prefix does. Clearly, the shorter prefixes certainly occur in it as well.So we've found that the number of new substrings that appear when the character
cis appended equalslen - z_max, wherelenis the current length of the string after appending the characterc.Consequently, the asymptotic complexity of the solution for a string of length n is O(n^2).
It's worth noting that in exactly the same way the number of distinct substrings can be recomputed in O(n) when a character is added to the beginning, as well as when a character is removed from the end or from the beginning.
#Philosophy
#2Why competitive programming problems?
In general, my goal is to somehow teach LLMs to think, in order to get closer to AGI. So why did I choose competitive programming problems, and not math, physics, geometry, chemistry or any other natural science field? Because the field of competitive programming problems:
- Is hard enough that solutions aren't trivial and require abstract thinking.
- Yields to logic and reasoning, like math, but unlike physics: physics requires physical experiments and the intuition of an agent living in the physical world.
- Lets you validate solutions automatically with tests or sites like CodeForces, unlike math.
- Lets you generate problems and validators automatically, by coming up with problems that have a trivial naive solution and a very complex fast solution; even ChatGPT can already write the naive solution today.
#2Is it really intelligence, and not memorization of the whole internet?
Now let's answer the question: has the neural network learned the whole internet and is just retelling it cleverly and skillfully, while we simply can't google well enough to find, for every question, the ready-made answer it has learned?
No. This is proven by the fact that the network can solve problems it has never seen before:
Dialogue
You have this competitive programming task:
Given string S, calculate sum of lengths of unique substrings of that string.
Could you please solve that task for string "BOBR" without writing any code?
Sure, I can help you solve this task without writing any code.
The string "BOBR" has the following unique substrings:
- "B"
- "O"
- "R"
- "BO"
- "OB"
- "BR"
- "BOB"
- "OBR"
Therefore, the sum of the lengths of these unique substrings is:
1 + 1 + 1 + 2 + 2 + 2 + 3 + 3 = 15
So the answer for the given string "BOBR" is 15.
You forgot "BOBR" itself
You're right, I apologize for the oversight.
In addition to the substrings I listed earlier, "BOBR" itself is also a unique substring of the given string "BOBR". Therefore, the sum of the lengths of all unique substrings of "BOBR" is:
1 + 1 + 1 + 2 + 2 + 2 + 3 + 3 + 4 = 19
So the answer for the given string "BOBR" is 19.
Was this problem on the internet? Of course not. Here you can see that the network is capable of some mental computation in the process of simply predicting the next word. Granted, the specific problem analyzed here is more questionable: some pieces of it are on the internet. But don't we all build our solutions out of pieces of what we've understood before?
#2LLMs as System 1
If you've read "Thinking, Fast and Slow" by Daniel Kahneman, you're familiar with the concepts of System 1 (intuition) and System 2 (thinking).
In my view, all neural networks are intuition. They give an answer instantly. If we compare this with human intuition, we can use such an instant answer very often, but not always. Sometimes you have to think. Moreover, thinking is built using intuition, and intuition is trained to give thinking the right directions to reason in, to stop it in time and to criticize it. That is, in a human they were trained together, which is why they can work together; you can't take some abstract intuition trained to predict who knows what and get working thinking out of it.
At this point I'd like to quote a research paper analyzing GPT-4:
Quote
These examples illustrate some of the limitations of the next-word prediction paradigm, which manifest as the model’s lack of planning, working memory, ability to backtrack, and reasoning abilities. The model relies on a local and greedy process of generating the next word, without any global or deep understanding of the task or the output. Thus, the model is good at producing fluent and coherent texts, but has limitations with regards to solving complex or creative problems which cannot be approached in a sequential manner. This points to the distinction between two types of intellectual tasks:
Incremental tasks. These are tasks which can be solved in a gradual or continuous way, by adding one word or sentence at a time that constitutes progress in the direction of the solution. Those tasks can be solved via content generation which does not require any major conceptual shifts or insights, but rather relies on applying existing knowledge and skills to the given topic or problem. Examples of incremental tasks are writing a summary of a text, answering factual questions, composing a poem based on a given rhyme scheme, or solving a math problem that follows a standard procedure.
Discontinuous tasks. These are tasks where the content generation cannot be done in a gradual or contin- uous way, but instead requires a certain ”Eureka” idea that accounts for a discontinuous leap in the progress towards the solution of the task. The content generation involves discovering or inventing a new way of looking at or framing the problem, that enables the generation of the rest of the content. Examples of discontinuous tasks are solving a math problem that requires a novel or creative application of a formula, writing a joke or a riddle, coming up with a scientific hypothesis or a philosophical argument, or creating a new genre or style of writing.
One possible way to interpret these limitations is to draw an analogy between the model and the concepts of fast and slow thinking, as proposed by Kahneman in [Kah11]. Fast thinking is a mode of thinking that is automatic, intuitive, and effortless, but also prone to errors and biases. Slow thinking is a mode of thinking that is controlled, rational, and effortful, but also more accurate and reliable. Kahneman argues that human cognition is a mixture of these two modes of thinking, and that we often rely on fast thinking when we should use slow thinking, or vice versa. The model can be seen as able to perform “fast thinking” operations to a very impressive extent, but is missing the “slow thinking” component which oversees the thought process, uses the fast-thinking component as a subroutine together with working memory and an organized thinking scheme. We note that a similar argument was made by LeCun in [LeC22], where a different architecture is proposed to overcome these limitations.
We already have examples of neural networks that form thinking: AlphaGoZero. If you don't know how it works, I recommend reading an article about it on Habr: AlphaGo Zero in really simple terms (in Russian). In AlphaGo the neural network is the intuition, and the Monte Carlo Tree Search algorithm (MCTS from here on) together with the neural network forms the thinking. I fell in love with this idea as soon as I read that article, back in 2017.
GPT networks are pure intuition, and moreover, intuition that wasn't trained together with any particular kind of thinking. That's why they can solve problems a little, and can even write code for what was in the training set, but they stumble over other, unfamiliar problems of the same difficulty.
Also, when a person actively strains their thinking to solve some problems, their intuition somehow develops along the way, so that it gives thinking more correct answers and lets it skip more reasoning steps. That is, in humans intuition and thinking combined create an endless stream of self-improvement when they face problems. I'd like to replicate this wonderful property of thinking.
#2There won't be enough data for AGI
I believe that no scaling laws will work: you can't teach GPT to think without deliberately building this into it, without high-quality data, or without giving it an environment where it gets feedback automatically. You can't feed it the whole internet, all the books, all the pictures, all the videos without any effort and get AGI. This requires deliberate work and inventing new techniques. It's roughly like expecting the neural network from AlphaGoZero to output the best move probabilities straight away, without MCTS (by the way, has anyone researched that 🤔).
I also believe that the stated task can't be solved with a specialized, very large dataset, the way AlphaCode did it. Yes, they created a super-intuition that can write code from a problem statement without reasoning, but it's still not thinking. And on top of that, they sample a million solutions there. I've never liked that paper at all.
There's also no adequate data showing how to think properly; such datasets have to be written by hand. Or the data does exist, but the network doesn't read it, doesn't understand it, doesn't analyze it, it just learns to predict the next word in it. Maybe if it ran some analysis prompts over every sentence on the internet and created training data from its own analyses, it would have learned to think long ago.
We don't have an infinite source of high-quality data that works in practice, so we need some way to generate it automatically. I propose using sites like CodeForces, where the network would try to solve simple problems (that it has never seen before), go through many approaches and many solutions, and then add information to the dataset about which approaches worked and which didn't.
#2Summary
- GPT networks are mostly System 1 (intuition).
- System 2 doesn't appear on its own, only in combination with some thinking algorithm.
- Stacking more layers won't work: there isn't that much high-quality data, and IMHO it's impossible to extract thinking from the current data with the next-word prediction approach.
- Training has to go through a feedback system, such as compilers or online judges.
#How a system for solving competitive programming problems should work
Such a system should think like a human: go through possible approaches, work through examples on paper, find insights.
It could look roughly like my last prompt, where the reasoning about solving the problem with the Z-function was written out. But of course it needs to be expanded.
To solve a problem, we need to find all approaches to solving it with the prompt "suggest several ideas for how this problem could be solved". This query can be run many times, and then the neural network can be used to remove duplicates.
An example of how ChatGPT answers such a prompt:
Dialogue
Please tell me how to solve this competitive programming task: given string S, you should calculate sum of lengths of all unique substrings of that string. For example, for string 'BOBR', you will get unique substrings: 'B', 'BO', 'BOB', 'BOBR', 'O', 'OB', 'OBR', 'BR', 'R'; sum of their length is 19. Please only tell list of ideas that can help to solve that task, without writing the code or writing explanation for each idea.
Sure, here are some possible ideas that could help in solving this task:
- Generate all possible substrings of the given string.
- Store each unique substring in a set or a hash table.
- Iterate over the set of unique substrings and sum their lengths.
- Use a trie data structure to efficiently store and count unique substrings.
- Use dynamic programming to efficiently generate and count unique substrings.
- Utilize a rolling hash or some other hashing technique to quickly check for duplicate substrings.
- Sort the substrings lexicographically, and then use two pointers to count the unique ones.
- Use the formula n*(n+1)/2, where n is the length of the string, to calculate the sum of all substrings, and then subtract the sum of lengths of duplicate substrings.
Note that some of these ideas might be more efficient or feasible than others depending on the length of the string and the constraints of the problem.
By the way, idea 8 is absolutely spot on: in the end that's exactly how the problem is solved with the Z-function.
Next, for each approach we ask it to generate all possible ways of using that approach. We've already seen the methods for the Z-function, so I'll write some for dynamic programming:
- A one-dimensional array,
DP[i]means how many unique strings there are in the suffix of size i. - A two-dimensional array,
DP[i][j]means whether a string is unique
Then an analysis can be run for each approach + way of using that approach.
The following prompts can be useful in the analysis:
- What properties does the resulting object have?
- Try to come up with input data that would refute this idea?
Inside the analysis we need to run not only general reasoning, but also an exploration of the approach on a concrete example. For example, the network makes up input data and tries to go through the edge cases:
- An empty string
- A string of one character
- A palindrome string
- A string of 8000 identical letters
- A string of random characters
And then for each case it works through the example "on paper" and sees how the idea works, maybe finding insights.
Then the insights can be extracted from each example and given to the network as input:
Solve the following problem: find the sum of lengths of distinct substrings.
Using: the Z-function, as follows: computing the Z-function for every suffix of the string.
Insights:
- you need to use the maximum of the Z-function;
- at each iteration, add the sum of lengths of the substrings in the current suffix minus the sum of lengths of the repeated strings;
- for the sum of lengths you can use the formula n*(n+1)/2;
Then we try to solve the problem with all possible approaches and all possible methods, generating several solutions for each leaf of the tree, and check them first on the data from the problem statement, and then on data we came up with ourselves (prompts can be devised for this too).
Next, for each solution we can estimate its time and memory complexity, both with the neural network and with data we may have generated earlier, or with a program we generated that comes up with large input data.
We submit the solutions and study the information about which one turned out to be correct, and which one failed and for what reason.
This is a foundation that can be extended with many different ideas. For example, subproblems can arise inside a single problem; for them you need to formulate a statement and ask the network to solve that problem separately. And of course this needs to be debugged in practice, because the possible facets of human thinking can be very numerous.
#How to collect data for such a system
For such a system to work, you need good data that describes the solutions to many problems in exactly this way. No cutting corners here: to begin with, such data has to be written by hand. You need to choose many different kinds of problems and have professionals write out their solutions. You may have to create lots of your own simple problems with an automatic checking system, just to make sure this works to any degree at all.
Suppose we've written plenty of data, trained the system, and it has solved its first problem outside the training set. What next?
We look at the logs of all the approaches to the problem that were tried and create new training data from them, which will develop the network's intuition:
- When an approach was being chosen, in the end we know which approach led somewhere, and what ended up working optimally and what was too slow or ate too much memory; then we create data:
- "<Problem statement>, if you solve this with the 'trie' approach, it will most likely be optimal in time, but not optimal in memory."
- "<Problem statement>, if you solve this with the 'dynamic programming' approach, you most likely won't be able to find a solution."
- The key phrase is most likely, because we're developing the network's intuition, and nobody can know this straight away without doing computation on the problem.
- Later this could probably be used to cut down on computation, or such data might somehow improve the network's intuition globally, in other domains.
- The same as the previous point, for when a method was being chosen for an approach to the problem.
- You can take the problem statement, then write the prompt "give a potential solution straight away, without reasoning", and write the correct code.
- We write the problem statement, then the code, and the prompt "determine the solution method from the code straight away", and write the solution method that produced this code.
- Run different methods of the same complexity on the same large data, measure their relative running time, and then train the network to estimate which solution is the fastest in terms of the constant factor, for example:
- "For <problem statement>, the 'trie' method is 1.5 times slower than the 'Z-function' method."
- "For <problem statement>, the 'trie' method takes 20 times more memory than the 'Z-function + a two-dimensional bool array marking whether a string is unique' method."
Next, we have many solutions for one approach/method, and we know which of them worked and which didn't. They can be used for training in the RLHF (Reinforcement Learning from Human Feedback) format, except that here the feedback comes from an automatic testing system.
By the way, the idea of producing a short text description of a solution from its code looks like a very promising direction, because then you can use all those millions of solutions that are publicly available on CodeForces to mine high-quality data about approaches to solving problems, which can later be used as hints in the system's normal problem-solving process. By the way, that's exactly why I don't like AlphaCode: they just train the network on people's solutions, without mining from them the useful, high-quality data that a human mines when looking at other people's solutions.
There's hope that from some point on, such a system could be let loose to bang its head against every possible problem on CodeForces, and after each new round of fine-tuning on data from newly solved problems, it would get smarter and smarter and solve more and more problems.
Fortunately, such a system will be extremely easy to interpret, because all its reasoning will be written in human language, and you'll be able to understand which exact aspect of the system needs tuning for a particular problem to get solved. Unlike AlphaCode, again. Here it will be very easy to involve people in improving the system.
#How this might not work
It may turn out that even GPT-4 is extremely rigid, and teaching it to think this way may require a huge amount of hand-written data.
The next problem I'm afraid of: we'll have to write the same thing from different points of view, in different wordings, because that's the only way a neural network can learn something well enough, or forget its old wrong solution patterns.
Or it may turn out that even if we teach it to solve very many problems at the level of a good competitive programmer, it won't be able to keep getting smarter, because solving new problems won't give it the intuition for solving harder ones.
#Conclusion
The proposed way of solving the problem is purely an engineering one and requires practically nothing on the machine learning side: no new architectures, no tricky math. It seems we've reached the point in progress where something like this could work.
Of course, I've only examined one problem this way (and it took me several weeks of working on weekends), and every new problem may bring new unusual difficulties that I can't cover in this article. I wrote it to pass on to you an idea and a philosophy that can be developed further as they collide with reality.
What do you think, is this a good direction to develop?
#Update after the release of o1, December 6, 2024
Literally yesterday a new version of o1 came out, and it managed to solve this problem!
But I had to add to the prompt after each of its mistakes.
Without all these prompt additions it kept trying to slip off toward a suffix array. Without that, it tried to make an O(n) solution with all sorts of tricks (which, of course, were wrong). Its mistakes were usually caught on the simplest example: ABB, so I added that to the prompt too. And once that happened, it finally managed.
Of course, the "Self-criticism" and "Possible reasons" sections still stand: part of this was already on the internet, so it got lucky figuring it out. Plus it writes itself that it's a "well-known formula". And I had to derive this formula myself :((
This isn't the kind of thinking I expected, but it's clearly a big step in the right direction! And, as I said, stacking more layers won't work; there's a good reason they added RL. I hope that at some point it starts thinking about how to refute its own thoughts; then it will be able to come up with ABB on its own. And of course we're waiting for it to get tools, so that it can write a naive version itself and then compare itself against the naive solution by running its code.
An even bigger problem for this model: how do you give it the ability to think for many hours, for example? Because stuffing EVERYTHING into the context is a bad way to do it. We'll need to come up with ways for it to compress the knowledge it has found into a short text and restart itself with a fresh context.
Now I need to find a new problem and evaluate models on it :)
Dialogue
You have that competitive programming task:
Given string S, calculate sum of lengths of unique substrings of that string.
How would you solve it using Z-function in most efficient way? You should use Z-function, not suffix array, not LCP, not hashing.
Result time complexity should be O(n^2), this task can't be solved in O(n).
After your solution please write a Python code of it.
For string ABA it should output 9, for string ABB 9 too.
Thinking for 1m 16s
Idea
We want to find the sum of lengths of all distinct substrings of a given string .
A well-known formula (from suffix arrays and LCP arrays) for counting distinct substrings is:
- The total number of distinct substrings of a string of length is:
where is the Longest Common Prefix array from the suffix array construction. Similarly, there is a known formula for the sum of lengths of distinct substrings:
But we are forbidden from using suffix arrays or LCP arrays directly. We must use the Z-function and the solution is allowed to be .
Key Insight Using Z-function
We can avoid building the suffix array. Instead, we can use the following trick:
-
Consider suffixes of : for .
-
For each suffix , consider the string:
where is a separator character not in the alphabet of .
Compute the Z-function for .
The part after corresponds to the original string . The Z-values in that part tell us how much of the prefix of appears starting at various positions in .
-
We are interested only in occurrences before (to detect previously seen substrings). That is, we look at the part of in corresponding to indices that represent starting positions in .
Formally, in :
The segment corresponds to .
We take the maximum Z-value in this segment (call it ). This tells us the longest prefix of that has appeared before position .
-
The number of new distinct substrings introduced by suffix is:
But we need the sum of lengths of these new distinct substrings.
The substrings contributed by suffix that are new are those from length up to .
The sum of these lengths is:
-
Summing this over all suffixes gives the total sum of lengths of distinct substrings.
Complexity
- For each , we construct of length approximately and compute the Z-function in .
- Summation over results in time.
This meets the requirement and uses only Z-function.
Example Check
For :
- For :
- No previous occurrences can appear before , so .
- Contribution = .
- For :
- Check first positions in -part of : found
- Contribution =
- For :
- Check first positions:
- Contribution =
Sum = 6+3+0=9, matches the sample.
Code Implementation
def z_function(s):
    n = len(s)
    z = [0]*n
    l, r = 0, 0
    for i in range(1, n):
        if i <= r:
            z[i] = min(r - i + 1, z[i - l])
        while i+z[i] < n and s[z[i]] == s[i+z[i]]:
            z[i] += 1
        if i+z[i]-1 > r:
            l, r = i, i+z[i]-1
    return z

def solve():
    S = input().strip()
    n = len(S)
    ans = 0
    for i in range(n):
        # Build T = S[i..] + '#' + S
        T = S[i:] + '#' + S
        Z = z_function(T)

        # We want max Z-value in T that corresponds to an occurrence before i in S
        # Those positions are T-index from (n-i+1) to (n-i+i)=n, inclusive.
        # i.e., T indices corresponding to S[0..i-1].

        start = n - i + 1
        end = start + i - 1  # last index corresponding to S[i-1]
        maxZ_i = 0
        if i > 0:  # If i=0, there's no previous suffix
            for t in range(start, end+1):
                if Z[t] > maxZ_i:
                    maxZ_i = Z[t]

        # Calculate contribution
        length_all = (n - i)*(n - i + 1)//2
        length_old = maxZ_i*(maxZ_i + 1)//2
        ans += length_all - length_old

    print(ans)
Explanation of Code
- We define a standard Z-function computation routine.
- For each suffix , we form and compute Z.
- We find
maxZ_iby looking only at the portion of Z corresponding to suffixes starting inS[0..i-1]. - Use the formula to accumulate the result.
- Print the final sum.
This will yield the correct answer in time, uses only Z-function, and matches the provided test cases.